
Getting started
Run the full Karet stack on your machine.
Just want to self-host?
This guide runs the compose file from a checkout of the karet repo, which also gives you the hash-password script. The self-hosting guide runs the same prebuilt images without a checkout, and covers configuration and updates.
Prerequisites
- Docker with the Compose plugin (
docker compose). - Node.js for the password hash script.
- About 3 GB of disk for the images (about 720 MB to download), plus the data you load.
1. Clone and configure
git clone https://github.com/karet-org/karet
cd karet

cat > .env <<EOF
POSTGRES_PASSWORD=$(openssl rand -hex 24)
KARET_SESSION_SECRET=$(openssl rand -base64 48)
KARET_WORKER_TOKEN=$(openssl rand -hex 32)
KARET_WEBHOOK_SECRET=$(openssl rand -hex 32)
EOF
Compose refuses to start without these, and without your admin password hash: run npm run hash-password and append the KARET_ADMIN_PASSWORD_HASH=... line it prints to .env. Defaults for any of them would let anyone in.
2. Start the stack
docker compose up -dFive services come up:
| Service | Port | Purpose |
|---|---|---|
web | :3000 | Karet's Next.js UI |
worker | :8080 | The Rust pipeline worker |
postgres | internal | Accounts, pipelines, config versions, job history |
rustfs | :9000 (:9001 console) | S3-compatible object store |
valkey | internal | Job queue and live job state |
3. Create the buckets
Karet stores data in three S3 buckets and does not create them automatically. Create them once against the bundled RustFS (using the default rustfsadmin credentials the stack ships with):
export AWS_ACCESS_KEY_ID=rustfsadmin
export AWS_SECRET_ACCESS_KEY=rustfsadmin

for b in karet-pipelines karet-lake karet-warehouse; do
  aws --endpoint-url http://localhost:9000 --region us-east-1 \
    s3api create-bucket --bucket "$b"
done
Or create karet-pipelines, karet-lake, and karet-warehouse from the RustFS console at http://localhost:9001.
4. Sign in
Open http://localhost:3000 and sign in as the admin whose password you hashed in step 1. Set your display name or change that password on Settings.
Pipelines you create are visible only to you and other instance admins until you grant someone access on the pipeline's Access page. See per-pipeline access.
5. Create your first pipeline
From the home page, click + New pipeline. Blank is selected by default; for this walkthrough pick Spending Tracker instead. That provisions:
Two months of sample transactions at
pipelines/<slug>/transactions/seed.csv.A source container at
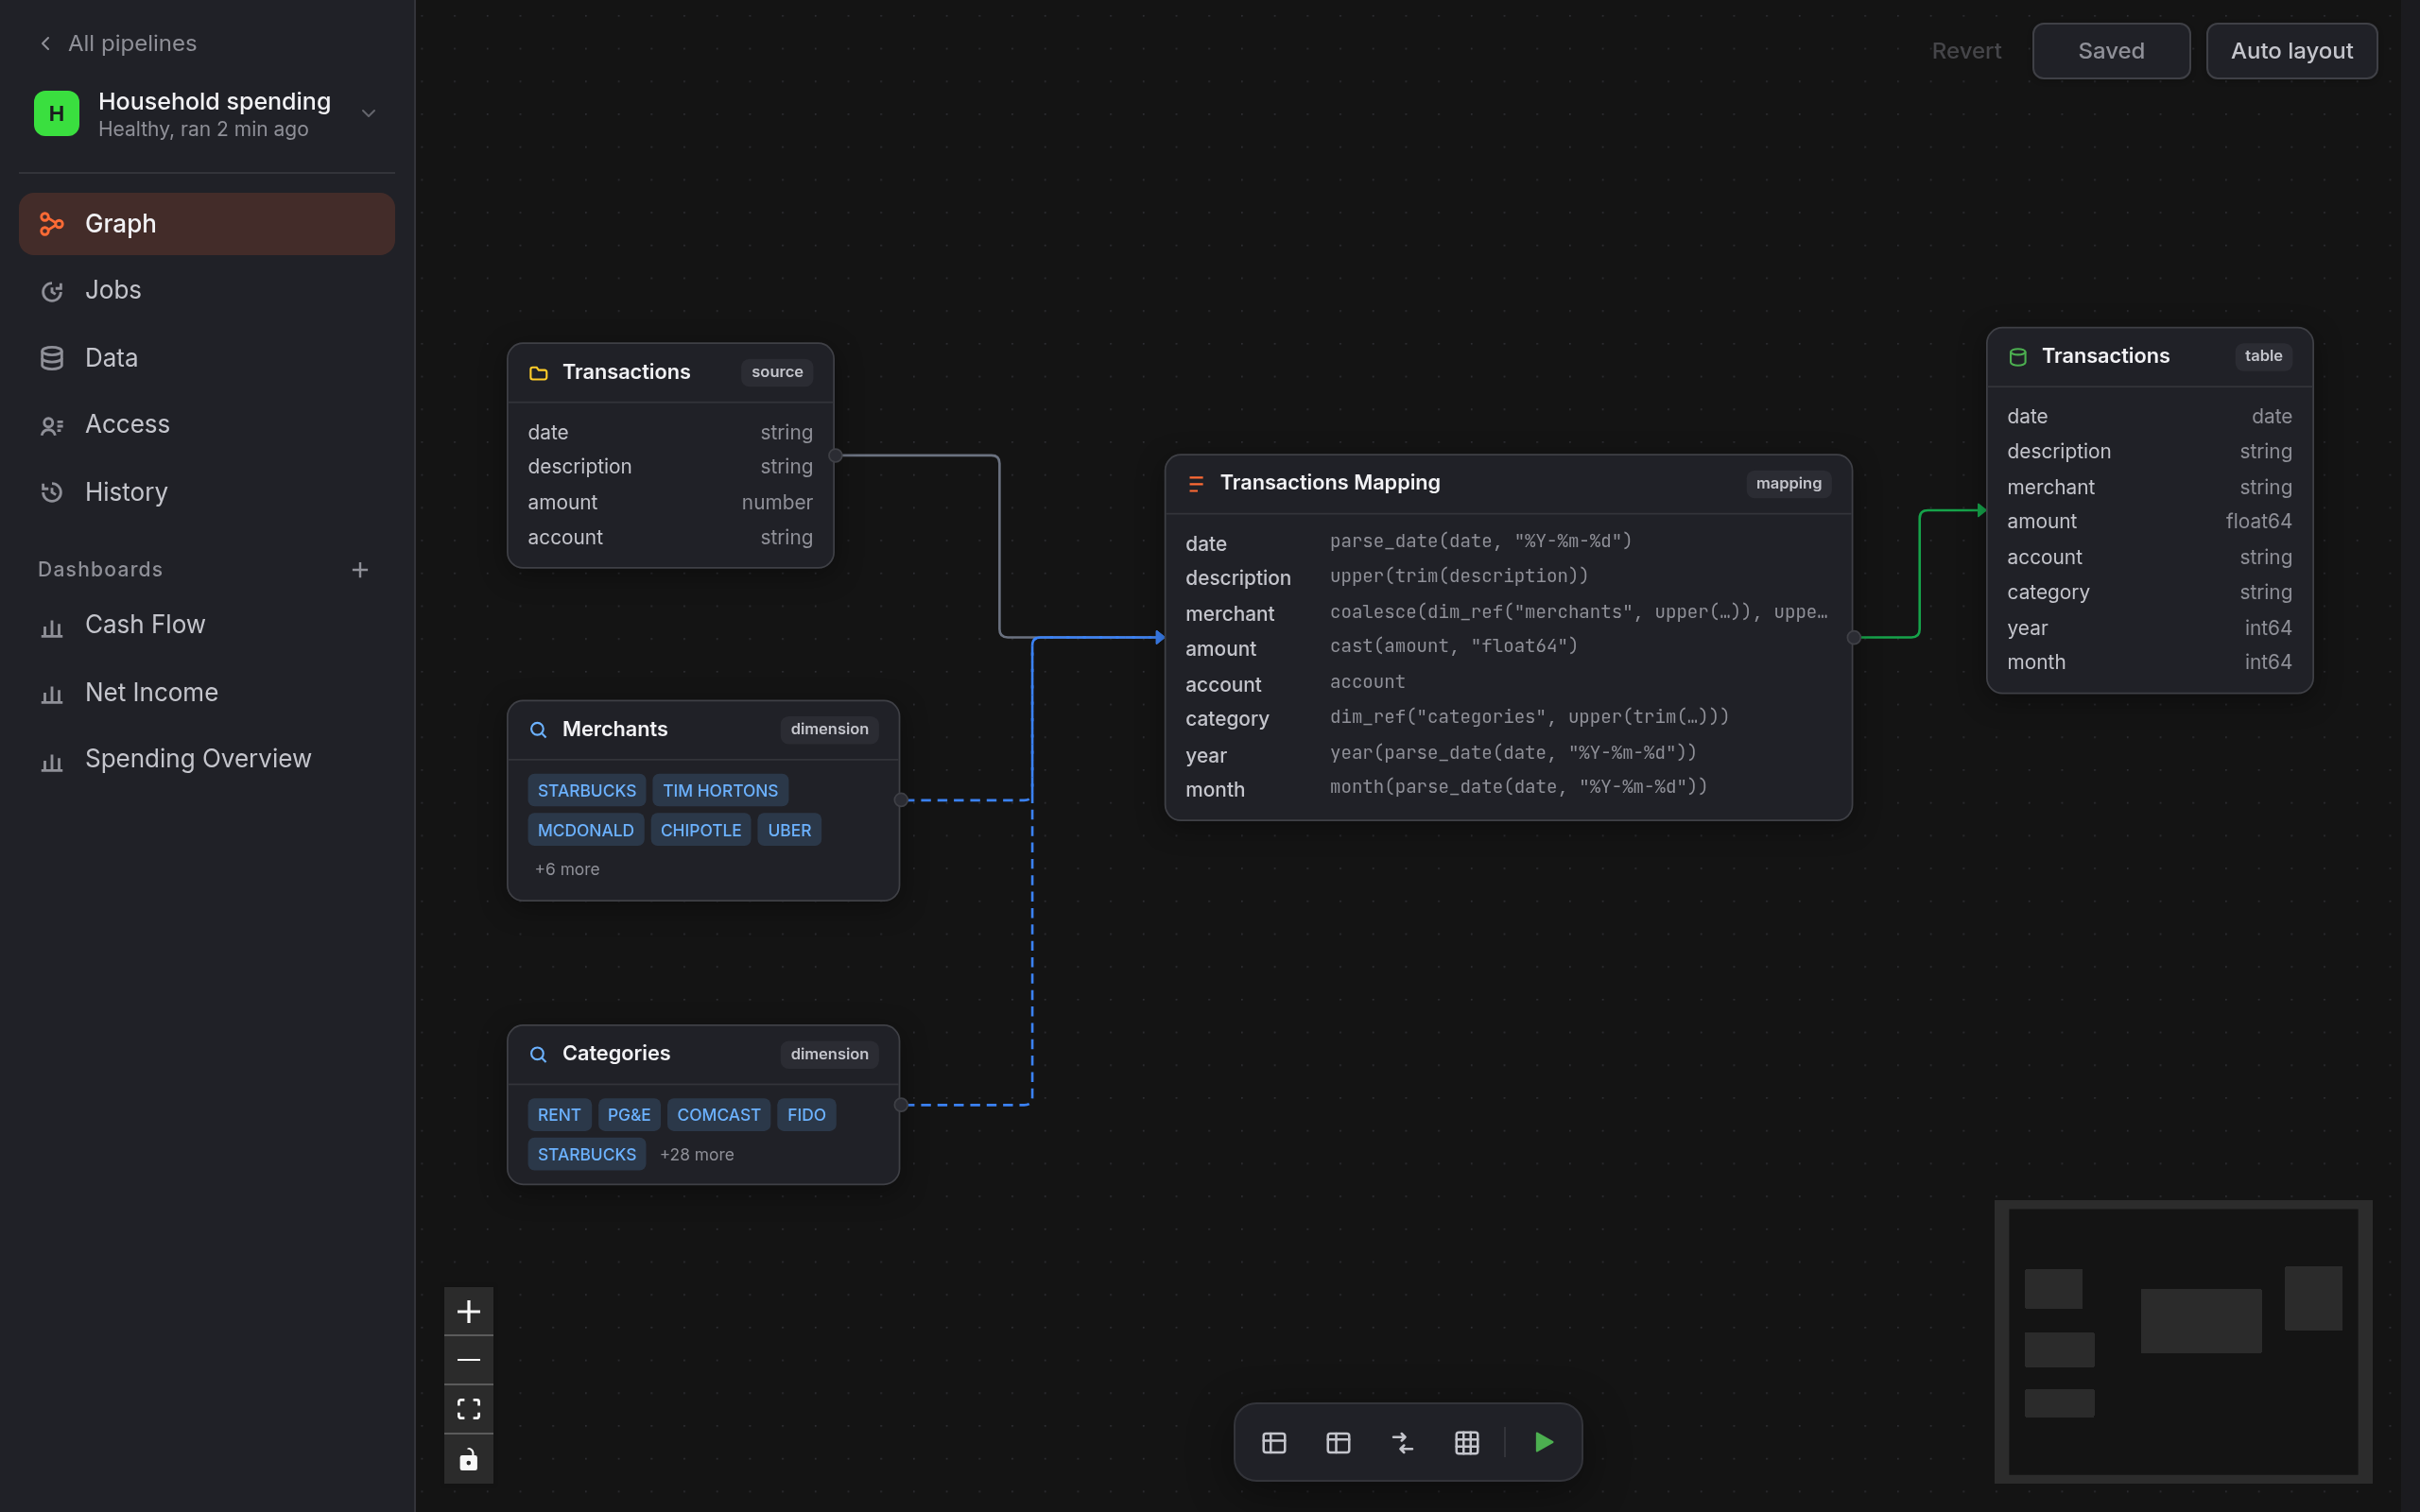
pipelines/<slug>/transactions/that expectsdate, description, amount, accountCSVs.Two dimensions: one tags each row with a category by keyword match, the other maps merchant names to a canonical spelling.
An analytic table written to
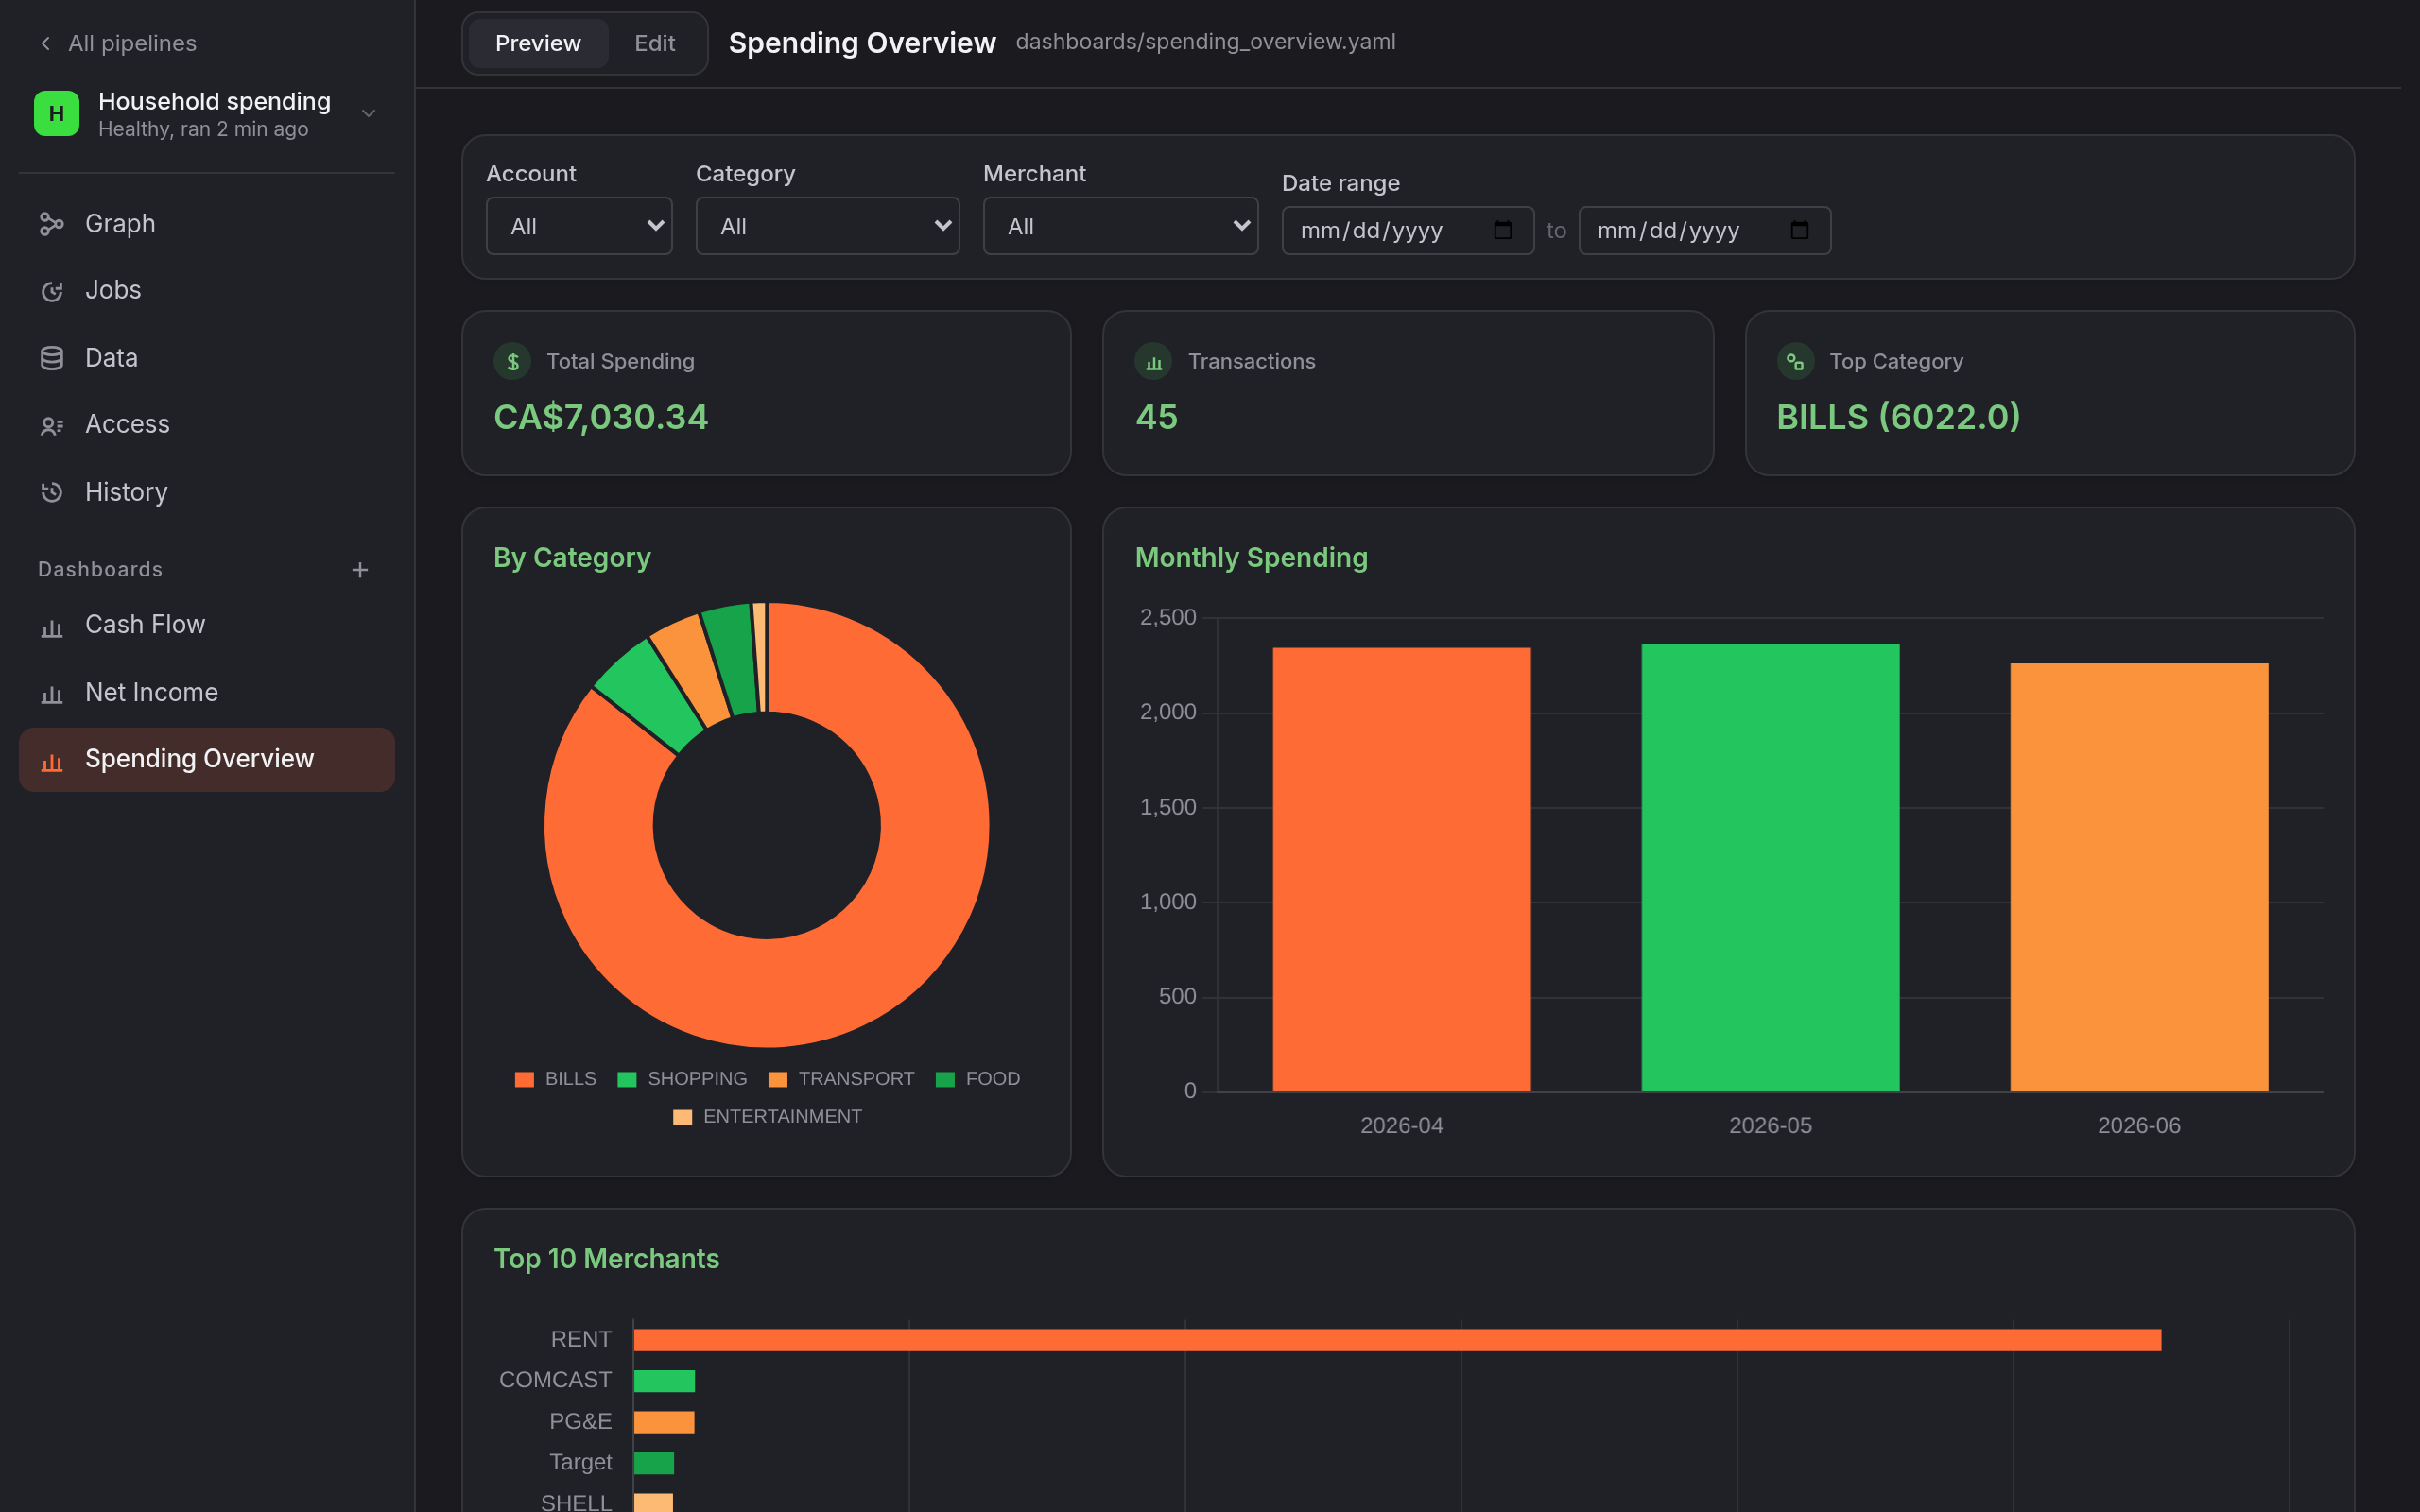
pipelines/<slug>/transactions/in the warehouse bucket as Parquet, partitioned by year and month.Three dashboards. Spending Overview has KPI tiles, a category doughnut, a monthly bar, a top-merchants bar and a transactions table; Cash Flow and Net Income cover money in and out.
The new pipeline appears on the home page:
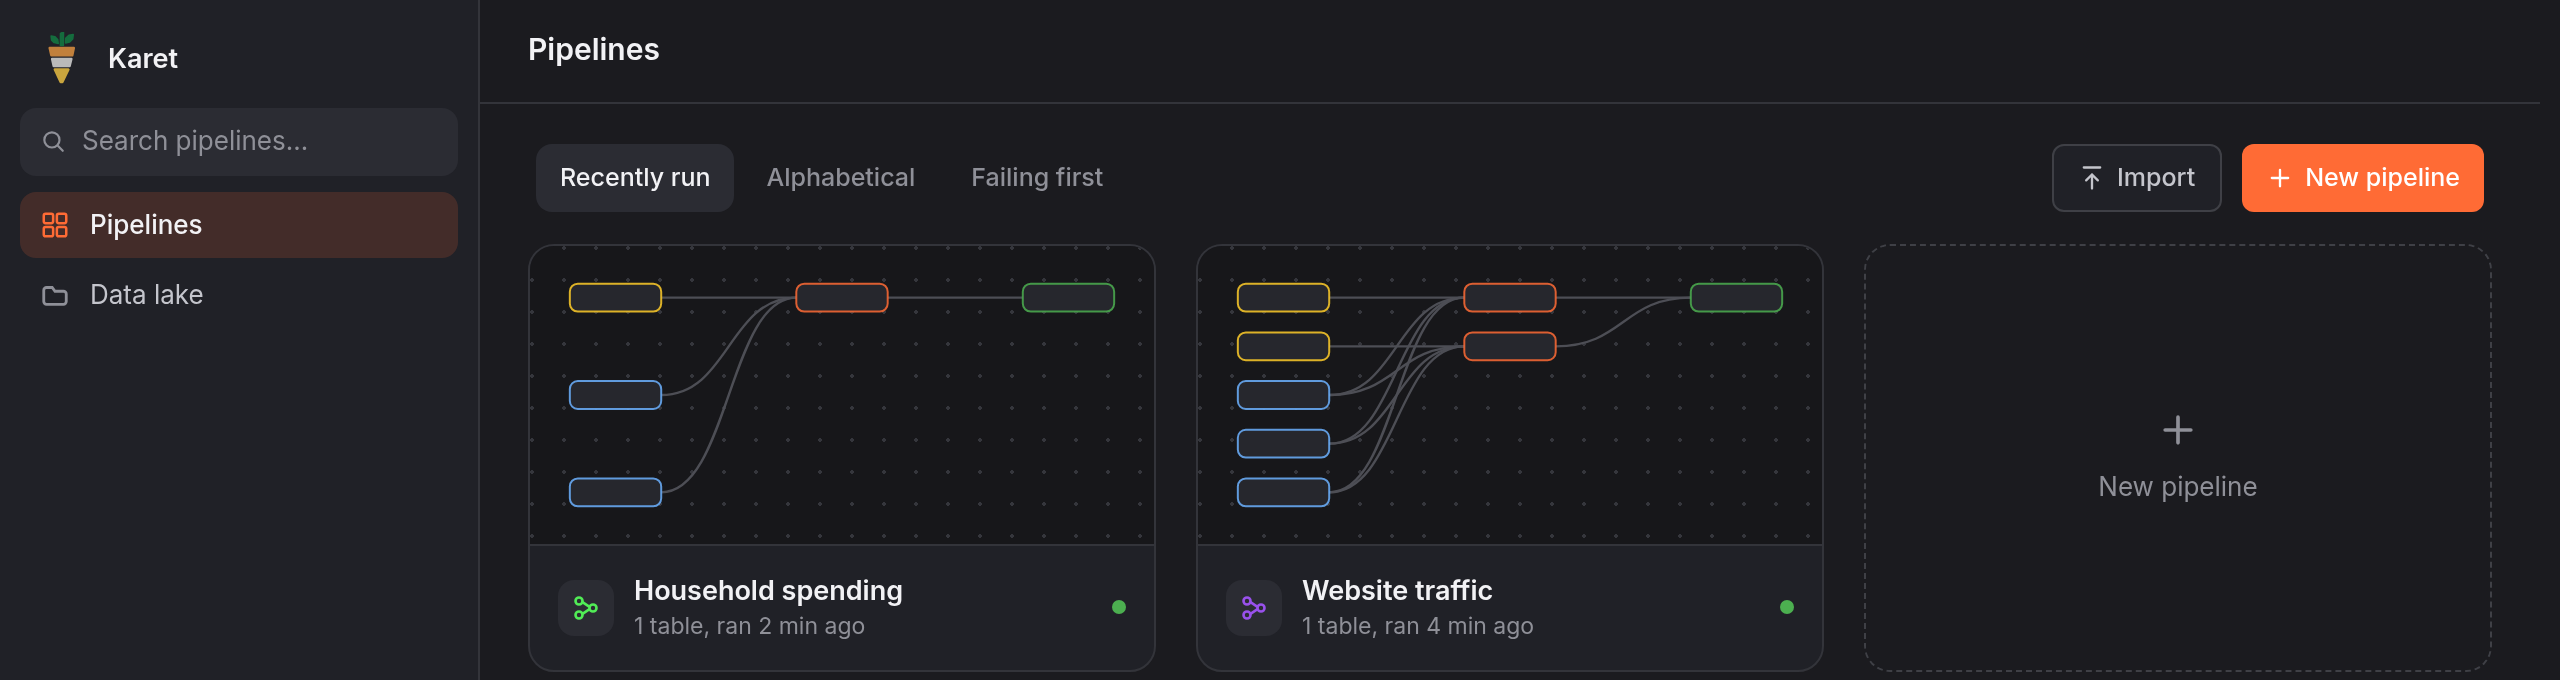
Open it to see its Graph: the source on the left, the dimensions below it, the mapping in the middle, and the analytic table on the right.
6. Run it, and add data
The sample data is enough for a first run. To add your own, upload CSVs with the same columns to the source prefix, from the Data lake page or the CLI:
aws --endpoint-url=http://localhost:9000 \
  s3 cp my-jan.csv s3://karet-lake/pipelines/<slug>/transactions/
Then click Run Pipeline on the Jobs page. Auto-runs can start a run on upload instead, with a 5-second debounce so a batch upload becomes one job; they need a one-time setup.
After the first run, a run reads only the files added since the last one; see incremental runs.
Until that first run finishes, the Data page says the table has no data yet. A table only exists in the warehouse once a run has published it, so there is nothing to query before then.
7. View the dashboard
Navigate to Dashboards → Spending Overview. KPIs, charts, and the transactions table all populate from the Parquet output.
What's next?
- Architecture: the services and how they connect.
- Pipeline config: the JSON shape that drives ingest.
- Dashboard config: panel kinds, layout, cross-filters.
- Auto-runs: wire RustFS uploads to pipeline runs.
- Search: find events by words and field values.
- Automating uploads: ship new data on a schedule.